
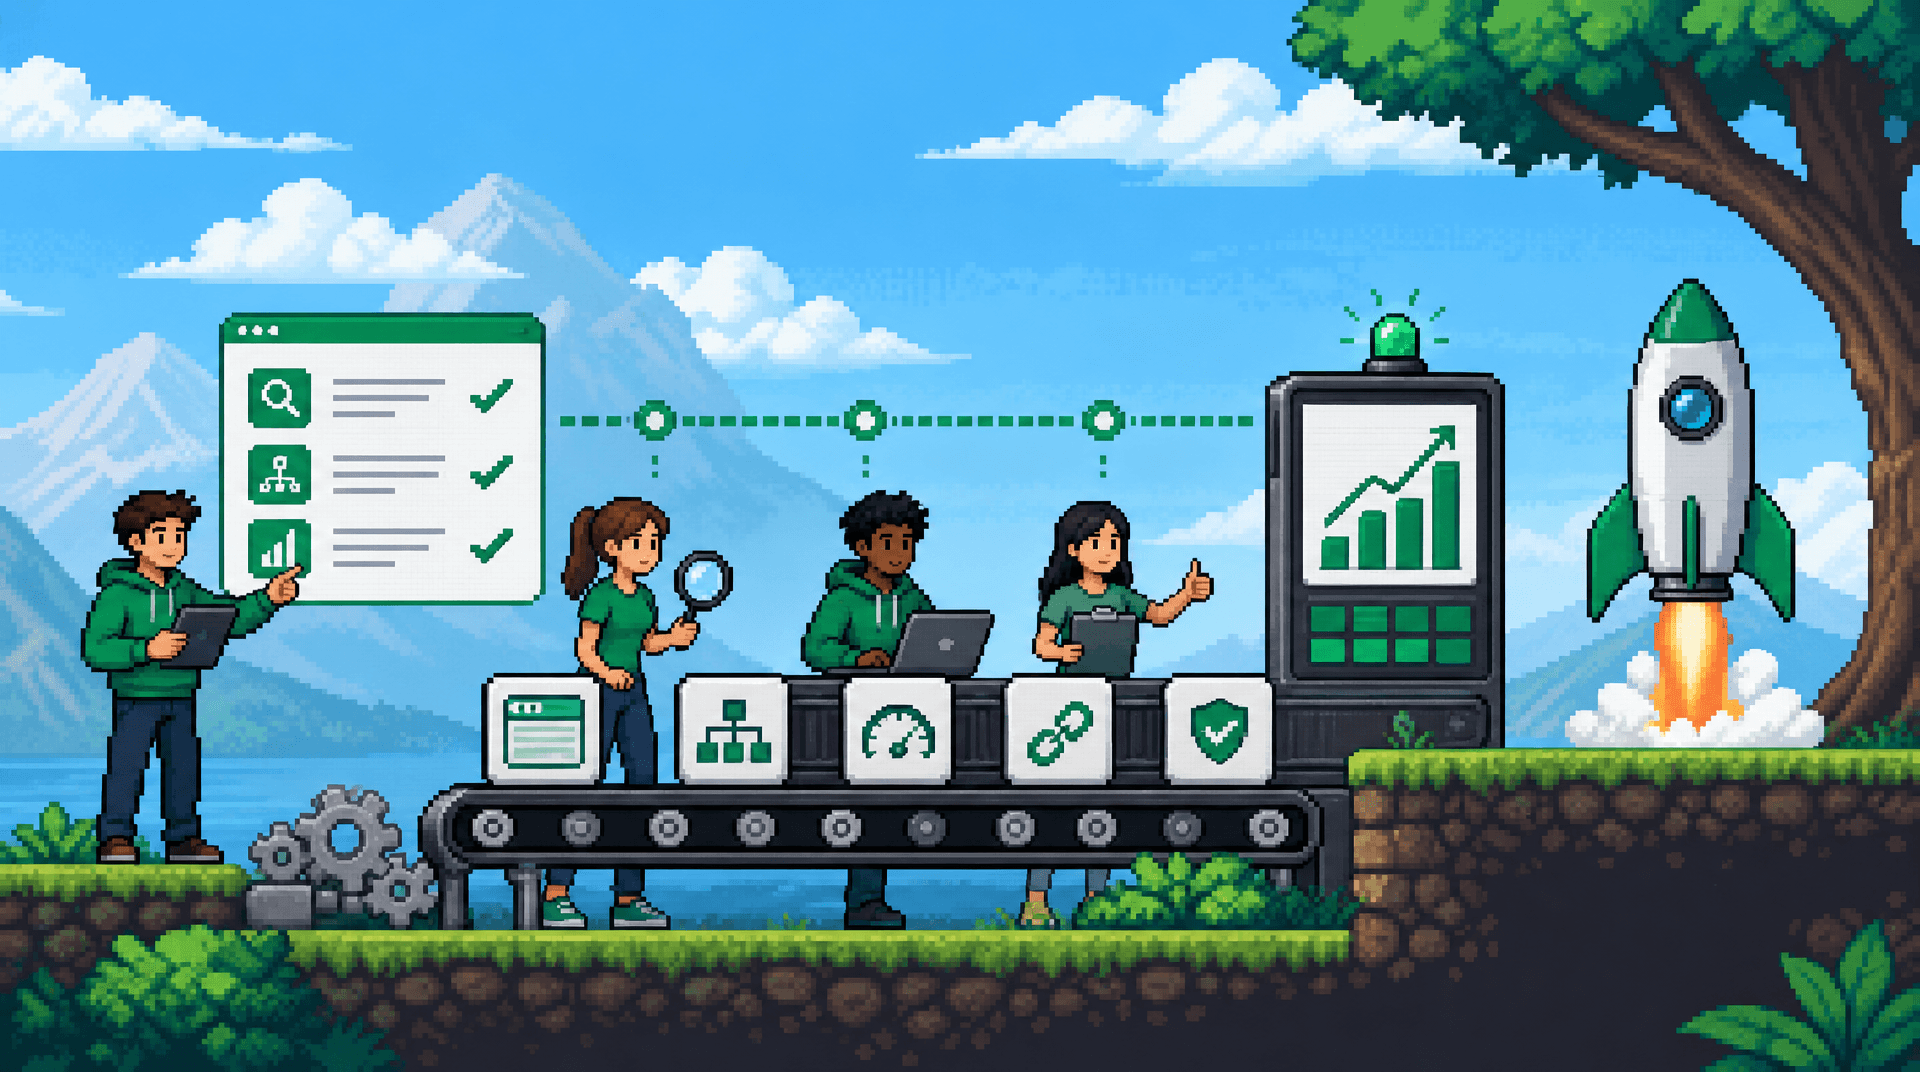
Search traffic can be lost in a single release even when the feature itself works perfectly. A page may return 200 while rendering an empty shell to crawlers, canonicalize to the wrong URL, or quietly remove the internal links that made it discoverable.
This guide shows product operators and engineering-adjacent growth teams how to build a repeatable technical SEO for product teams release workflow. The takeaway is simple: treat search-critical requirements as testable release contracts, with clear owners, automated checks, and explicit go or no-go gates before production.
Why Technical SEO Needs a Release Gate
SEO regressions are usually integration failures, not isolated “SEO mistakes.” A routing change can alter canonical URLs, a component refactor can remove semantic headings, and a CMS migration can leave thousands of generated pages orphaned. None of those failures is reliably caught by a generic functional QA pass.
A release gate makes organic visibility part of the product quality definition. It does not require every engineer to become an SEO specialist. It requires the team to identify the search surfaces affected by a change and verify a small set of observable contracts.
Define the search-critical surface area
Start every ticket by classifying its likely impact. The key question is not whether a release was requested by the growth team. The question is whether it changes a URL, content, rendered HTML, link graph, crawl directive, structured data, or page performance behavior that affects search.
Typical search-critical changes include route updates, pagination, filtering, authentication states, template components, metadata utilities, redirects, design-system updates, and API responses that populate indexable pages. Programmatic SEO work deserves particular attention because one template defect can propagate across an entire page set.
Turn requirements into release contracts
A release contract states what must remain true after deployment. For example: “Each public integration page has one self-referencing canonical, a unique title, a server-rendered H1, and at least three contextual internal links.”
Contracts should be specific enough to test and narrow enough to assign. Avoid vague acceptance criteria such as “page is SEO-friendly.” A useful contract names the expected output, the route set, the validation method, and the accountable owner.
Assign Owners Before Code Reaches QA
A robust workflow removes ambiguity without forcing growth to approve every commit. Product, engineering, content, and growth each own different decisions, while a named release owner decides whether exceptions are acceptable.
Use a lightweight responsibility model in the pull request or release ticket. The goal is to surface decisions while they are cheap to reverse, rather than asking who owns a traffic loss after it reaches production.
Separate implementation from acceptance
Engineering owns implementation quality: routes resolve, rendering works, directives are correctly emitted, and test coverage reflects the intended behavior. Growth or technical SEO owns search acceptance criteria: indexation policy, canonical intent, page eligibility, internal-link rules, and measurement expectations.
Product owns scope and tradeoffs. If a launch must proceed with a known SEO limitation, product records the exception, its user impact, the affected URL pattern, and a remediation date. That keeps risk visible instead of normalizing silent debt.
Use a practical RACI for release decisions
The following model works for most product teams, including teams shipping SEO architecture for SSR React applications.
| Release activity | Product | Engineering | Technical SEO or growth | Content |
|---|---|---|---|---|
| Classify SEO impact | Accountable | Consulted | Responsible | Consulted |
| Implement template and routing changes | Consulted | Responsible | Consulted | Consulted |
| Define indexation and metadata rules | Consulted | Consulted | Accountable | Responsible |
| Run automated checks | Informed | Responsible | Consulted | Informed |
| Approve a documented exception | Accountable | Consulted | Responsible | Informed |
This is not a bureaucracy layer. It is a way to prevent a content writer from owning a redirect rule or an engineer from guessing whether filtered URLs should be indexed.
Build the Technical SEO QA Checklist
The checklist should run against a deploy preview or staging environment that resembles production. It should use representative URLs, not only the homepage or a newly created test page. Include an existing high-value route, a newly generated route, a paginated route, an empty state, and a route with optional parameters.
Verify crawlability and indexation controls
Confirm the final HTTP behavior first. Check status codes, redirect chains, robots directives, canonical tags, XML sitemap inclusion rules, and robots.txt behavior. A page intended to rank should generally return a stable 200 response, be crawlable, and declare a canonical consistent with its intended indexable URL.
Conversely, pages that create low-value duplication, such as internal search results or certain filtered states, need an intentional policy. Do not use noindex as a substitute for fixing uncontrolled URL generation. If crawlers can create unlimited parameter combinations, constrain links, parameters, routes, or faceted navigation behavior at the source.
Test rendered HTML, not only the browser view
A browser can execute client-side JavaScript and make a page look complete even when the initial document is thin. For SEO architecture for SSR React, inspect the raw response and compare it with the rendered DOM. Critical copy, headings, canonical tags, robots meta tags, internal links, and structured data should be available in the intended server response.
Run this check on a sample across templates, not one URL per release. Template-level systems need sample-level validation because conditional logic often fails on long names, missing images, unpopulated fields, special characters, or locales.
Validate metadata and structured data as template outputs
Metadata is a data contract, not decoration added at the end of a launch. Test that titles and descriptions are unique where required, headings match page intent, canonical tags are absolute and correct, Open Graph fields do not expose staging domains, and language annotations follow the actual localization strategy.
If structured data is used, validate syntax and eligibility rules, but do not assume valid markup guarantees enhanced search appearance. Focus first on whether the markup accurately represents visible page content and remains consistent when source data is incomplete.
Automate Checks That Can Block a Release
Manual review is valuable for relevance and editorial quality, but it is weak at catching repeated mechanical failures. Automation workflows for product teams should turn predictable checks into CI jobs that generate evidence with every preview deployment.
Start with a small blocking suite. A fragile, oversized crawler that developers ignore is less useful than a fast set of tests tied to the routes and contracts changed in the pull request.
Use three layers of automated validation
Unit tests validate metadata functions, URL builders, route normalizers, and robots-policy helpers. Integration tests validate real route responses with representative data. Crawl or browser tests validate linked page sets, final markup, status behavior, and cross-page rules.
The table below maps common checks to the most reliable validation layer.
| Check | Best validation layer | Blocking when |
|---|---|---|
| Canonical URL generation | Unit and integration | Canonical is missing or differs from policy |
| SSR content and H1 | Integration | Search-critical content is absent from HTML |
| Redirect behavior | Integration | A changed route creates loops, chains, or 4xx responses |
| Internal-link minimums | Crawl test | A target template becomes orphaned or underlinked |
| Sitemap and robots rules | Integration and crawl test | Indexable pages are excluded or restricted |
Store artifacts with the build: response headers, HTML snapshots, crawl output, and a route diff. When a regression occurs, these artifacts reduce diagnosis time and make it possible to identify whether a defect began in code, content data, or deployment configuration.
Add threshold-based QA gates
A gate should express a release decision, not merely produce a report. For example, block deployment when any intended indexable route returns a non-200 status, when a canonical points to staging, when required SSR content is absent, or when new pages have no qualifying internal links.
Use warnings for issues that need judgment, such as title similarity, unusually short copy, or a decline in links compared with the prior build. Define who reviews warnings and how long an exception can remain open. An exception without an owner and due date is simply an untracked failure.
Test Internal Links and Programmatic SEO at Scale
Internal linking is often broken by component changes rather than deliberate decisions. A redesigned card may omit its destination anchor, a pagination update may hide deep URLs, or a conditional component may remove related-page links on sparse data. These failures affect discovery and topical relationships even when every page remains technically indexable.
Model internal links as graph rules
Write rules at the template level. A solution page might link to its parent category, two sibling pages, a use-case page, and an editorial guide. A programmatic SEO page may need links to its category hub, neighboring entities, and one human-curated explanatory resource.
Then crawl the preview and test graph properties: no intended page has zero inlinks, links resolve to canonical destinations, anchors are descriptive where context permits, and navigation does not create unbounded parameter URLs. The right minimum depends on the site, so establish a baseline before enforcing a threshold.
Sample the long tail deliberately
Do not QA only the best-populated records. Test records with missing descriptions, long strings, symbols, no related entities, multiple locales, and recently added data types. These are the cases where template logic, escaping, pagination, and fallback metadata tend to fail.
For a large rollout, split release validation into two phases. Validate the template and representative sample before publishing, then crawl the full production URL set after release. This keeps deployment practical while still verifying that real data did not create systematic defects.
Release, Monitor, and Close the Feedback Loop
The production deploy is a checkpoint, not the end of quality assurance. Some behaviors only emerge in production because of CDN rules, edge redirects, robots files, sitemap generation, authentication middleware, or environment-specific configuration.
Run a post-release verification window
Immediately after deployment, test a small set of production URLs across critical templates. Confirm status codes, final canonicals, page source, headers, robots behavior, and key internal links. Compare the production output with preview artifacts rather than relying on memory.
For major migrations or programmatic launches, monitor coverage and crawl signals in the relevant search tools, server logs where available, error monitoring, and your own crawl reports. Investigate directional changes by segment: template, directory, locale, or release cohort. Sitewide averages can hide a template-level failure.
Convert incidents into durable controls
When an issue escapes, avoid adding a generic “be more careful” step. Identify the missing contract or test. If a CDN appended a noindex header, add a production header assertion. If entity pages became orphaned, add an inlink rule to the crawl gate.
This is where growth execution playbooks compound. Each incident should produce a clearer owner, a better fixture, an automated assertion, or a documented exception path. Over time, the team spends less effort rediscovering known failure modes.
Key Takeaways
- Treat technical SEO for product teams as a release-quality concern, not a post-launch audit.
- Define search contracts for routes, rendering, metadata, crawl controls, and internal links before implementation.
- Assign distinct ownership for implementation, search acceptance, and risk exceptions.
- Block releases on deterministic failures and use warnings for issues requiring editorial judgment.
- Validate production output and turn escaped defects into new automated controls.
A release workflow built around evidence and clear decisions protects organic growth while allowing product teams to ship with confidence.