
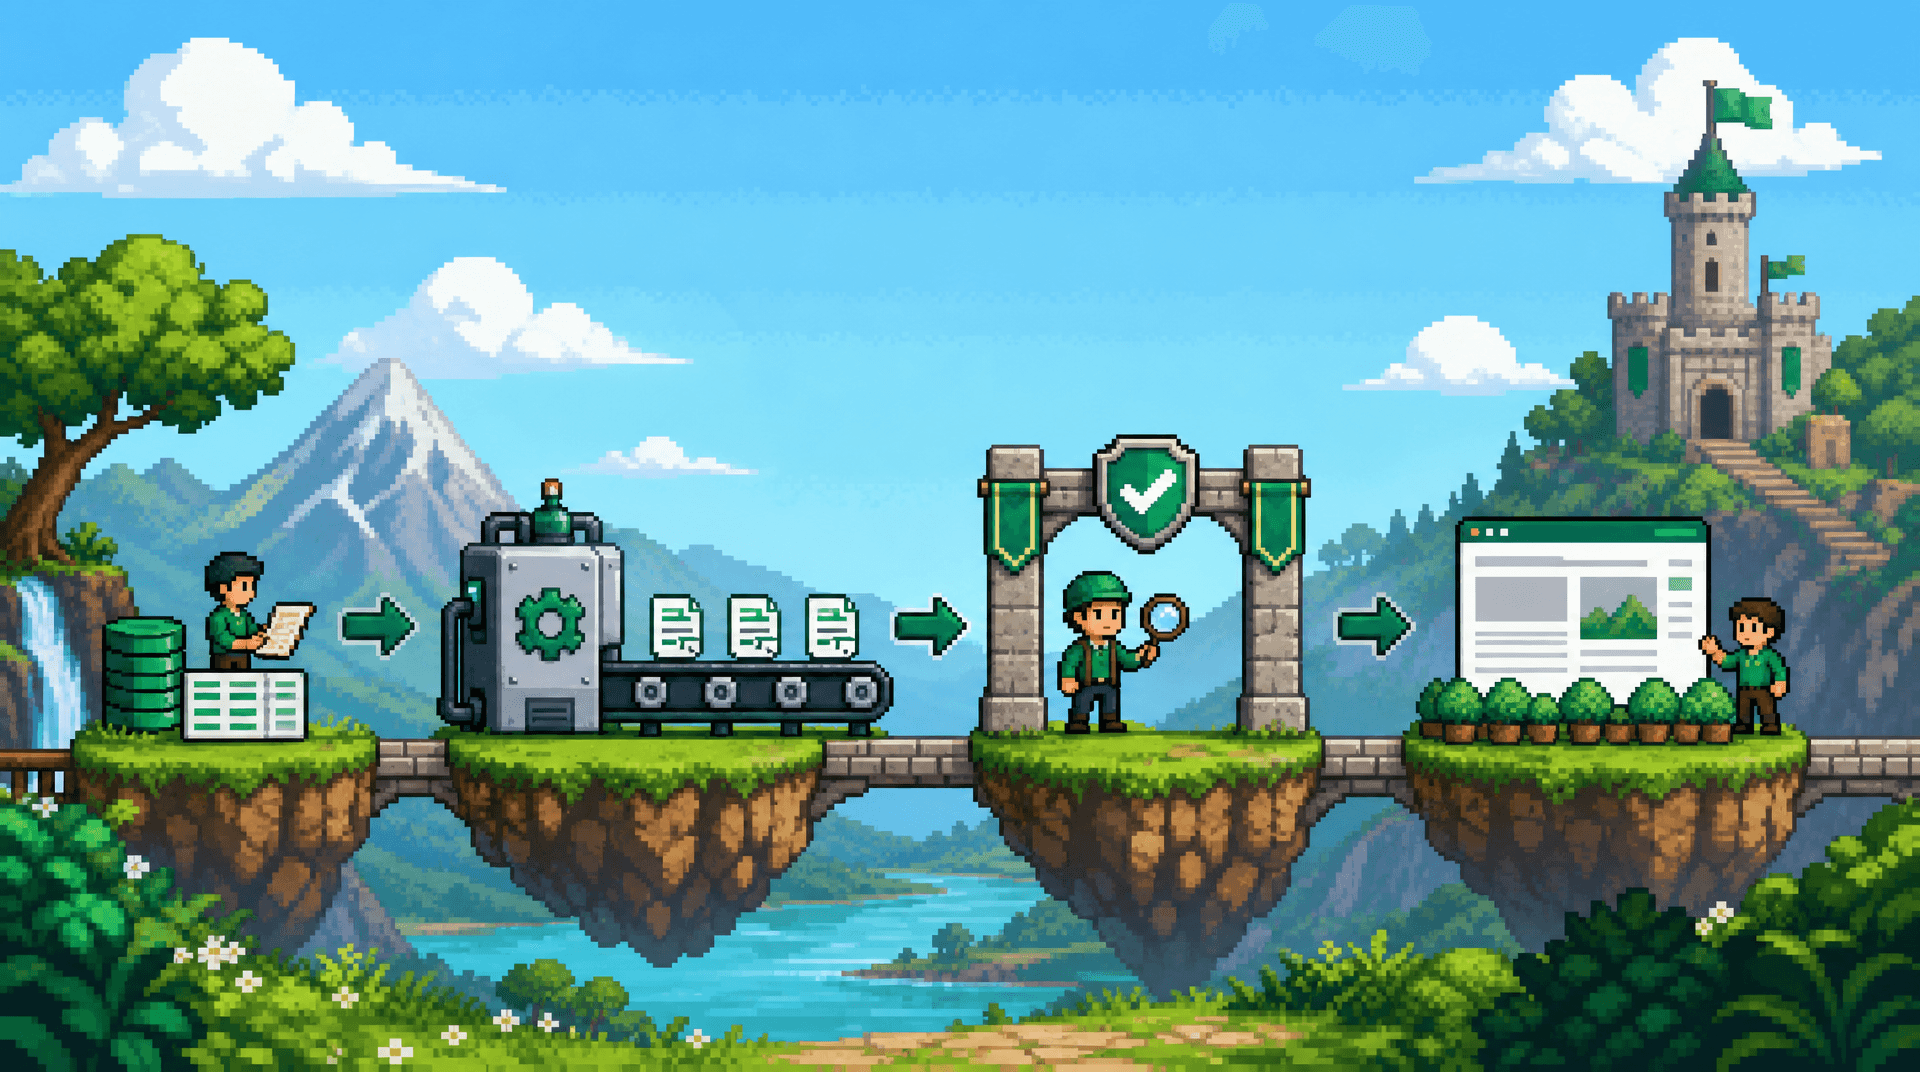
Programmatic SEO fails when a team treats page generation as the finish line. The difficult work is deciding which pages deserve to exist, proving the underlying data is reliable, and preventing small template defects from becoming thousands of indexed problems.
This guide shows product operators and technical growth teams how to build a programmatic SEO workflow that produces useful, crawlable pages at scale. The key takeaway is simple: connect intent-led templates, governed data, SSR rendering, and release gates so quality is a property of the system, not a manual cleanup task.
Define the Page System Before You Generate URLs
A programmatic site is a set of page types, each with a distinct job in a search journey. Start with a page system, not a spreadsheet of keyword combinations. For every proposed template, document the query pattern, audience, decision it supports, source fields, unique-value requirement, and internal-link role.
A useful test is whether a reader can make better progress after landing on the page. If the answer is only that the URL contains a keyword, the template is not ready for production.
Map query patterns to genuine jobs to be done
Group demand by the modifier that changes the reader's task. For a technical product, common patterns include integrations, use cases, alternatives, implementation guides, industry-specific workflows, and feature comparisons. A page targeting "[product] integration with [platform]" should answer a different question than "[platform] automation workflow."
Define the minimum useful information for each pattern. An integration page may need setup prerequisites, supported actions, authentication constraints, example workflows, troubleshooting notes, and links to relevant documentation. A use-case page may need the operational problem, implementation sequence, ownership, outputs, and measurement plan.
Set a publish threshold for every template
Not every possible entity deserves a page. Establish hard conditions before an entity enters the publishing queue, such as complete mandatory fields, a valid canonical topic, supporting internal links, and enough differentiated content to satisfy the query.
The following matrix separates valid page expansion from thin permutations.
| Template type | Required unique inputs | Strong reason to publish | Common reason to block |
|---|---|---|---|
| Integration page | Capabilities, setup details, constraints | Specific implementation intent | Only a partner name changes |
| Use-case page | Workflow steps, role, measurable outcome | Distinct operational problem | Generic benefits repeat |
| Comparison page | Verifiable differences, fit criteria | Evaluation-stage query | Unsupported feature claims |
| Location or industry page | Relevant rules, examples, terminology | Material context changes | Geography is cosmetic |
This threshold is the first QA gate. It protects the site from building indexable inventory that neither users nor search engines can distinguish.
Build a Governed Data Pipeline
Templates are only as good as the data that fills them. Treat the content source as a production dataset with ownership, validation, and versioning rather than a loose collection of CMS fields.
The pipeline should move from source collection to normalization, enrichment, validation, preview, and publish. Keep the stages explicit so a broken feed does not silently create broken pages.
Create a content schema with field-level rules
For each entity, define required fields, allowed values, source of truth, update owner, and fallback behavior. A product integration record, for example, might contain display name, slug, category, supported events, authentication method, setup URL, compatibility notes, status, and last-reviewed date.
Avoid weak fallback copy such as inserting "not available" into a prominent section. If a critical field is missing, fail the record or hide the section only when the page still meets its usefulness threshold. The correct behavior depends on the template, so make it a documented rule instead of an ad hoc developer decision.
Normalize entities and control taxonomy drift
Entity inconsistency creates duplicate URLs, fragmented internal links, and contradictory copy. Normalize names, aliases, categories, dates, and identifiers before rendering. Maintain a canonical ID separate from the display label so editorial changes do not alter routing or analytics joins.
Taxonomies also need governance. If contributors can create near-identical categories such as "CRM," "CRMs," and "customer relationship management," filtering and related-page modules will decay. Use controlled vocabularies and route proposed new values through review.
Enrich data without fabricating claims
Automation workflows for product teams can classify, summarize, or draft structured descriptions, but generated output must not become a source of truth. Keep factual claims linked to approved source fields, first-party documentation, or reviewed editorial inputs.
A practical pattern is to separate deterministic fields from assisted fields. Deterministic fields drive facts and routing; assisted fields propose summaries, examples, or metadata that enter a review queue when they affect a material claim.
Design Templates That Add Information Value
A reusable template should provide a stable reading experience while leaving room for entity-specific evidence. Repeating the same paragraph with one token swapped is not scalable content design. It is a signal that the page type has no differentiated information model.
Start by listing what must vary, what can stay consistent, and what must be omitted when data is incomplete. Then build modular sections that map directly to query intent.
Use modular blocks with clear eligibility rules
Common modules include a contextual overview, requirements, implementation steps, examples, limitations, related entities, and next actions. Every module needs an eligibility rule. For instance, render an "example workflow" only when the record has enough approved inputs to describe a real sequence without speculation.
This protects quality more effectively than forcing every page into the same visual length. A shorter page with complete, specific information is preferable to a long page padded with generic FAQs or repeated sales language.
Prevent duplication at the page and cluster level
Check duplication in two directions. Page-level duplication asks whether a page has enough distinct copy and data compared with another URL. Cluster-level duplication asks whether several templates compete for the same query and offer nearly the same answer.
Use canonical topics to decide ownership. If an integration overview and an integration setup guide both exist, assign one to broad discovery and one to implementation intent, then link them deliberately. Do not let both target the identical head term with interchangeable introductions.
Implement SEO Architecture for SSR React
SEO architecture for SSR React must make the first response complete and consistent. Search engines and users should receive the meaningful page title, primary content, structured data where appropriate, canonicals, and internal links without depending on client-side hydration.
Rendering is not merely a framework setting. It is a contract between routing, data availability, cache behavior, and the indexable document returned for every valid URL.
Render critical content on the server
Server-render the primary content blocks, metadata, breadcrumb links, and navigational relationships. If a data fetch is essential to the page's search value, it belongs in the server-side render path or a pre-generation process, not behind a client-only request.
Handle failures explicitly. A transient upstream error should not produce a 200 response with an empty shell that can be crawled and indexed. Choose defined behavior for each case: retry during build, serve a controlled temporary error, use approved stale content, or exclude the route until the data is valid.
Make indexation and canonicalization deterministic
Generate one canonical URL format for every entity. Normalize trailing slashes, casing, tracking parameters, pagination conventions, and filter combinations. Any URL that cannot represent a unique search result should be redirected, canonicalized, or marked non-indexable according to its function.
For large collections, produce XML sitemaps from the same eligible-record set that drives publishing. Include only canonical, indexable URLs with successful renders. A sitemap is an inventory declaration, not a dumping ground for every route your application can resolve.
Build internal links as a graph, not a footer
Internal linking should express relationships users expect: category to entity, entity to related use cases, comparison to alternatives, and guide to implementation pages. Use deterministic rules plus editorial overrides for high-value clusters.
Track orphaned pages and shallow link patterns. If a generated page has no contextual inbound link, its existence is difficult for both users and crawlers to discover. Distribution loops for SEO should also feed proven external demand back into these internal clusters rather than sending every campaign to a generic hub.
Add QA Gates to the Publishing Workflow
QA gates turn quality standards into release criteria. They should run before publication, after deployment, and after indexation signals begin to arrive. The goal is not to create a bureaucratic approval queue, but to stop defects at the cheapest point to fix them.
Assign each gate an owner, a pass condition, a failure action, and evidence. A check without a response path becomes dashboard theater.
Run pre-publish data and content gates
Before a record is eligible, validate required fields, slug uniqueness, taxonomy membership, claims status, copy completeness, internal-link availability, and template applicability. Run automated similarity checks to surface unusually repetitive pages, then sample the highest-risk records for human review.
Human review should focus on judgment-heavy issues: whether the page resolves the intended task, whether examples are credible, whether terminology matches the audience, and whether the page creates a misleading promise. Review the template with representative edge cases, not only the best-populated records.
Run deployment and crawlability gates
After rendering, test the actual HTML response rather than only component output. Confirm status codes, titles, meta descriptions, canonical tags, robots directives, structured data validity, hreflang where applicable, image alt behavior, and links.
Use a small canary set before a full rollout. It should include a normal record, a sparse record, a record with special characters, a long name, a recently changed record, and an intentionally blocked record. This set catches route encoding, fallback, and caching failures that happy-path previews miss.
Use a release scorecard with stop conditions
The scorecard below gives each team a concrete definition of ready. Adjust thresholds to your risk tolerance, but keep blocking conditions unambiguous.
| Gate | Evidence | Pass condition | Failure action |
|---|---|---|---|
| Data integrity | Schema validation report | Required fields and IDs are valid | Hold affected records |
| Content value | Template and sample review | Distinct, intent-matched information | Revise template or block cluster |
| Technical render | HTML and crawler tests | Correct indexable response and metadata | Fix deployment before release |
| Link coverage | Internal-link graph check | Eligible pages have contextual paths | Add modules or editorial links |
| Post-launch health | Search and crawl monitoring | No systemic errors or duplication pattern | Pause rollout and remediate |
Measure Quality After Launch and Feed It Back
Publishing is the start of a learning loop. Monitor the cluster by template, data state, and release cohort, not only as one aggregate traffic line. This makes it possible to identify whether a performance problem comes from intent selection, content coverage, rendering, linking, or data quality.
Use growth execution playbooks that specify when to observe, when to iterate, and when to stop expansion. Adding more URLs before understanding the first cohort compounds uncertainty.
Track leading and lagging indicators
Leading indicators include successful renders, crawl requests, indexation coverage, canonical consistency, internal-link discovery, and template-level error rates. Lagging indicators include qualified organic entrances, engagement with the next relevant action, assisted conversions where measurement supports it, and retention of rankings for the intended query class.
Interpret signals in context. Low impressions may mean weak demand, poor discovery, or a mismatch between title and query. A high exclusion rate may point to duplication, weak value, canonical confusion, or technical response issues. Investigate the system layer before rewriting individual pages at random.
Operate a controlled iteration loop
Release a bounded cohort, annotate the deployment, inspect technical and search signals, then make one or two attributable changes. Examples include adding a missing unique module, tightening eligibility rules, improving contextual internal links, or correcting metadata generation.
Maintain a decision log with the hypothesis, template version, affected URLs, checks run, observed outcome, and next action. Over time, this becomes a reusable operating manual rather than institutional knowledge held by one engineer or SEO lead.
Key Takeaways
- Build programmatic SEO around distinct search tasks and minimum information thresholds, not keyword permutations.
- Govern source data with schemas, canonical IDs, controlled taxonomies, and clear rules for assisted content.
- Use SSR React to return complete, indexable HTML with deterministic canonical, sitemap, and internal-link behavior.
- Gate releases across data, content value, technical rendering, and post-launch health before expanding a cohort.
- Measure results by template and release cohort so the team can improve the system instead of patching isolated URLs.
A durable programmatic SEO workflow makes scale safer: every new page inherits a tested operating system for usefulness, crawlability, and continuous improvement.