
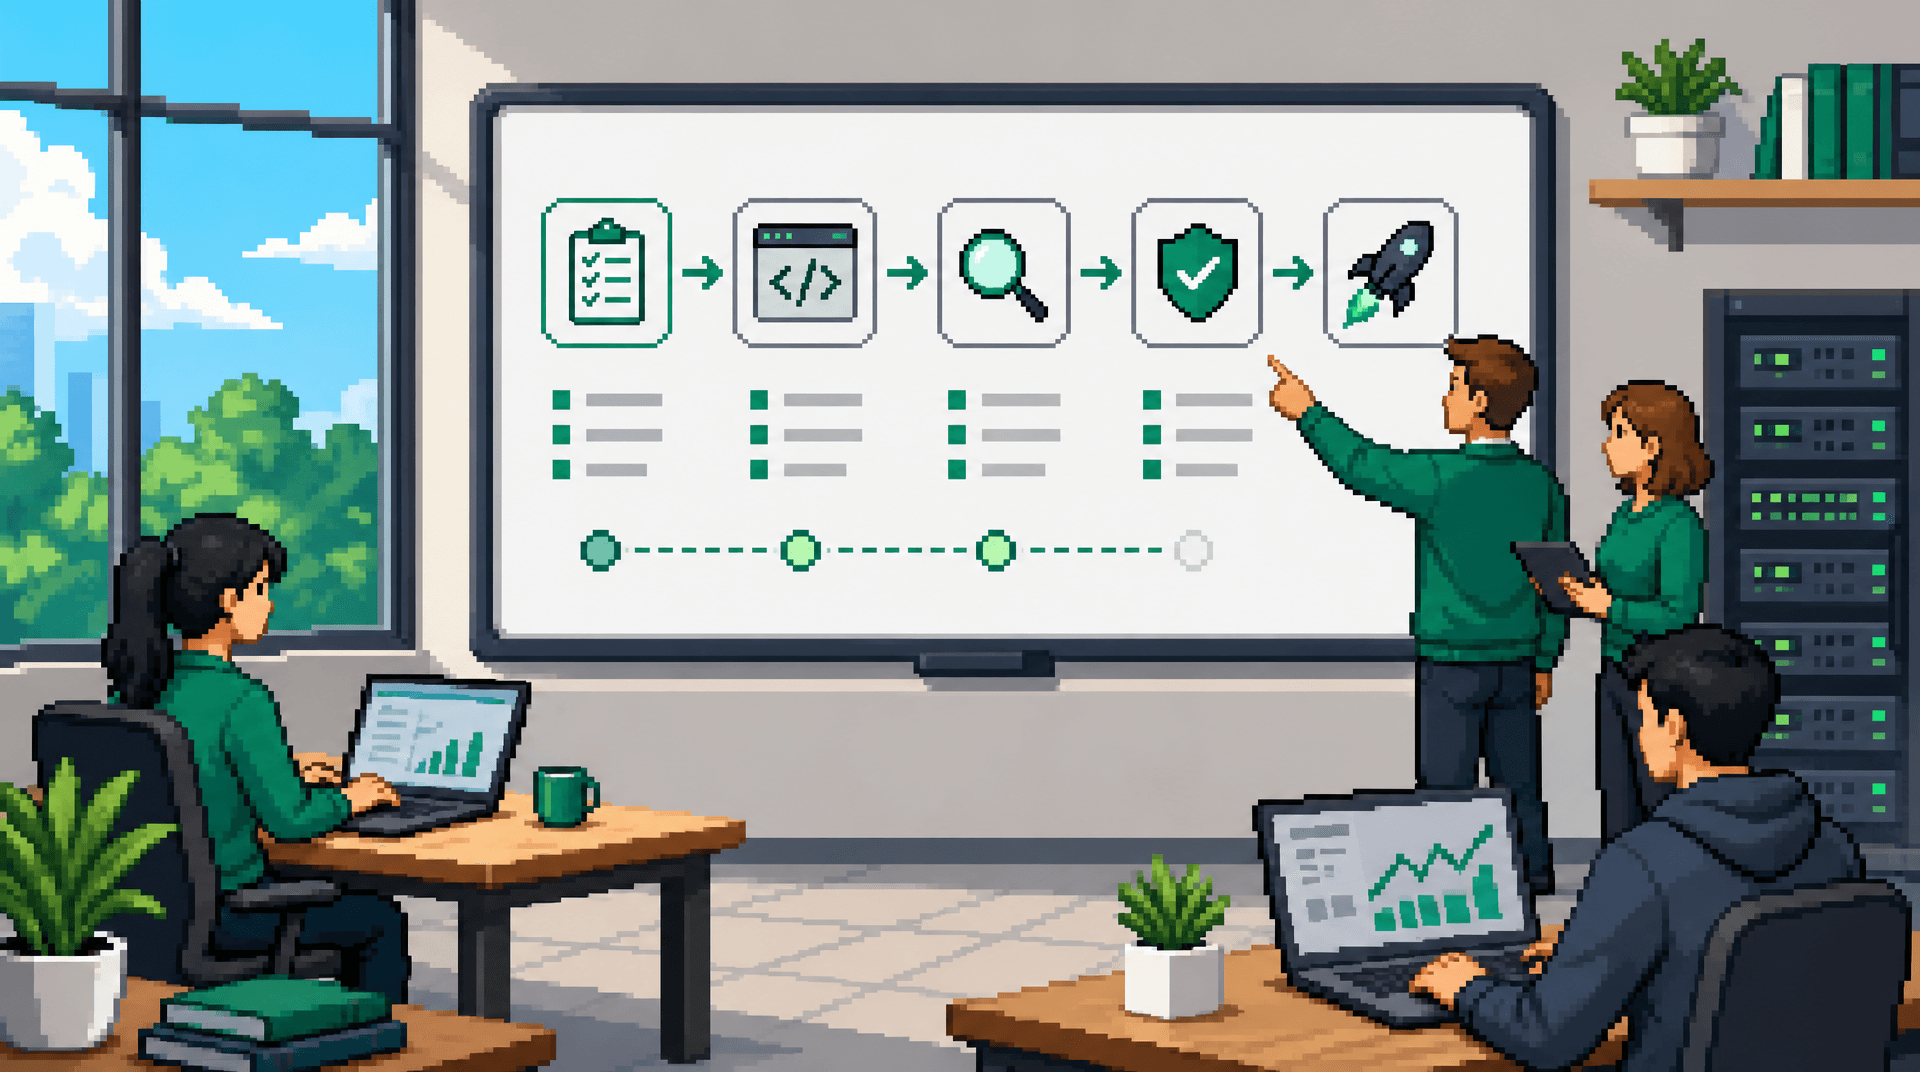
Technical SEO rarely fails because a team does not know the basics. It fails when a routing change, rendering refactor, experiment, or content deployment reaches production without anyone verifying what search engines can actually crawl, render, index, and understand.
This guide explains how to build a technical SEO release process for product teams shipping frequently in SSR React applications and other dynamic stacks. It is for product managers, engineers, SEO leads, and growth operators who need repeatable controls rather than one-off audits. The key takeaway: treat SEO as a release quality attribute, with explicit ownership, automated checks, risk-based QA, observability, and a tested rollback path.
Why Technical SEO for Product Teams Needs a Release Process
SEO changes are often distributed across teams. Engineering owns templates and infrastructure, product owns prioritization, content owns page inputs, and growth or SEO owns search requirements. Without a shared process, each group can assume another group tested the outcome.
A release process turns broad requirements such as “make this page indexable” into testable conditions. It also makes tradeoffs visible before a change affects thousands of URLs, which is especially important for programmatic SEO.
SEO defects are production defects
A 200 status code is not proof that a page is eligible to rank. A page can return successfully while shipping a noindex directive, an incorrect canonical, client-only primary content, blocked resources, malformed structured data, or an internal-linking regression.
For a product team, these issues affect discoverability, acquisition efficiency, and the integrity of landing pages that support product distribution. They should be evaluated with the same discipline used for payment flows, analytics events, or accessibility regressions.
Risk grows with template reach
The correct QA depth depends on blast radius, not on whether a request is called “SEO work.” A title change on one editorial page is low risk. A shared component change that alters canonicals, robots directives, pagination, JSON-LD, or rendered copy across every directory page is high risk.
Use a risk tier to decide review requirements and release controls.
| Risk tier | Typical change | Required control |
|---|---|---|
| Low | Metadata on a small set of pages | Peer review and URL spot check |
| Medium | New page template or internal-link module | SEO review, staging crawl, representative URL tests |
| High | Routing, SSR, canonical, robots, sitemap, or global template change | Automated gates, approval, controlled rollout, monitoring, rollback plan |
The point is not to slow every release. It is to reserve deeper verification for changes that can create sitewide search losses.
Define Ownership and a Release Contract
A durable workflow begins before a ticket enters a sprint. Teams need a release contract: a small, agreed set of facts that defines what must be true when a change ships and who confirms each condition.
Assign a directly responsible owner
The product or engineering owner remains accountable for release readiness. The SEO or growth owner supplies requirements, acceptance criteria, and risk context. QA validates execution against the agreed checks, while content operations owns data quality when page copy, entities, or inventories are generated from a pipeline.
Avoid assigning SEO approval to a vague group. Name a reviewer for high-risk changes and establish a fallback when that person is unavailable. A process that depends on an informal Slack message will break during fast releases.
Write testable acceptance criteria
Requirements should be observable in a browser, a raw HTTP response, a crawler, or a monitoring tool. “SEO-friendly” is not an acceptance criterion. “The canonical is self-referential for indexable parameter-free URLs” is.
For each affected template, capture:
- Target URL patterns and representative examples
- Indexation intent: index, noindex, redirect, or canonicalize
- Expected title, meta description, heading, and primary content source
- Canonical, robots meta,
X-Robots-Tag, pagination, and hreflang behavior where relevant - Structured data types and required properties
- Internal-link sources and expected crawl paths
- Sitemap inclusion rules and exclusion rules
- Success metrics, owner, launch date, and rollback trigger
For programmatic SEO pages, include the data contract. Specify which fields are required to create a valid page, what happens when data is missing, and when a page must not be published. This prevents thin, duplicate, or incomplete URLs from being created merely because a database row exists.
Build SEO Architecture for SSR React Into the Pipeline
Modern rendering stacks can support strong search performance, but only if the release process tests the server-delivered document rather than relying on what an authenticated developer sees after hydration.
Validate the initial HTML response
For indexable routes, inspect the raw response from staging and production. Confirm the initial HTML contains the unique title, canonical tag, robots directive, key headings, primary content, and crawlable links. If the application intentionally uses client-side rendering for a portion of the page, document why that content is nonessential for indexing.
In SSR React environments, common regressions include metadata being added only after hydration, different server and client route resolution, cached head tags, and error boundaries that produce a soft 200 response. Test anonymous requests without local cookies or feature flags.
A practical command-level check can be as simple as retrieving a page with curl, saving the HTML artifact in CI, and asserting expected values. The goal is not to make every SEO test fragile. It is to catch high-impact output changes before deployment.
Test route and URL-state behavior
Search engines need a stable mapping between valuable content and preferred URLs. A release should test trailing slash policy, case normalization, locale paths, query parameters, duplicate filters, expired records, and redirects from retired routes.
Create a route matrix for each material change. It identifies what should happen for valid, duplicate, unavailable, and malformed URLs.
| URL condition | Expected behavior | SEO reason |
|---|---|---|
| Preferred indexable URL | 200, self-canonical, indexable | Establishes the ranking target |
| Tracking parameter variant | 200 with canonical to preferred URL | Consolidates duplicate signals |
| Obsolete equivalent URL | Single-hop permanent redirect | Preserves useful equity and user path |
| Removed page with no replacement | 404 or 410, excluded from sitemap | Avoids soft-404 inventory |
| Invalid filter combination | 404 or controlled noindex | Limits low-value crawl paths |
Keep this matrix in the ticket or repository beside route logic. It is more useful than a generic “check redirects” item because it states the desired product behavior.
Add QA Gates Before, During, and After Deployment
A good gate produces evidence, not ceremony. It should be automated when the condition is deterministic, and manually reviewed when judgment matters, such as copy usefulness or entity coverage.
Run pre-merge checks in CI
For medium- and high-risk changes, build a representative URL fixture set. Include a standard page, a long-tail page, a page with missing optional data, pagination states, a localized route if applicable, and an expired or invalid route.
Run checks against the built application or staging preview for status codes, redirects, canonical values, robots directives, page titles, heading presence, structured data parseability, and internal-link targets. Fail the build for clear violations, such as a production template returning noindex or a canonical pointing to a non-200 URL.
Do not attempt to encode every SEO judgment into a unit test. Keep automation focused on invariants. That makes failures actionable and reduces the temptation to bypass noisy gates.
Use a staging crawl for template changes
Before release, crawl the staging environment or an authenticated preview that accurately represents production output. Compare the new crawl with a baseline when a broad template, navigation, or programmatic page generator changes.
Review deltas in indexability, canonical targets, title duplication, headings, response codes, link counts, sitemap entries, and structured-data errors. A crawl is particularly valuable when a component change affects URLs that unit tests did not enumerate.
Require a production smoke test
Deployment can alter headers, caching, redirects, edge behavior, and environment variables. A release is not complete until the team checks production for a small set of representative URLs.
The smoke test should verify the raw HTML, browser output, response headers, canonical and robots signals, sitemap accessibility, and key internal links. Record the tested URLs and result in the release ticket. This creates an operational trail without requiring a lengthy report.
Roll Out Programmatic SEO Changes Safely
Programmatic SEO magnifies both good systems and bad assumptions. One generator can create useful pages at scale, but a weak data rule or template bug can create a large inventory of duplicates, empty pages, or crawl traps.
Start with a controlled cohort
Ship a limited cohort before generating the full inventory. Choose entities that represent normal data, edge cases, and meaningful search intent. Validate page quality, indexation rules, internal-link discovery, performance, and conversion instrumentation before expanding.
Cohort releases also create a feedback loop for product teams. Search Console coverage patterns, server logs, crawl results, and user behavior can expose problems that were not visible in staging, such as parameter discovery or unexpectedly sparse pages.
Gate publication on quality signals
A URL should not be published just because it can be rendered. Define minimum requirements for unique value, complete required data, correct taxonomy placement, non-duplicative intent, and a valid internal-link path.
For example, a location-plus-integration page might require a verified location entity, an active integration record, a unique explanatory module, and at least one related-link destination. If those conditions are not met, keep the page out of the sitemap and navigation until it qualifies.
This is where automation workflows for product teams help most. A workflow can validate inputs, produce a preview, assign exceptions to an owner, and publish only after QA gates pass. Automation should reduce repetitive review, not automate the creation of unqualified URLs.
Monitor Search Behavior and Define Rollback Criteria
Monitoring closes the gap between “deployed” and “working.” Many SEO failures are delayed because crawlers revisit pages on their own schedules, so teams should track leading indicators immediately and search performance trends over time.
Watch leading indicators first
Immediately after launch, monitor error rates, response code distribution, redirect chains, cache behavior, robots headers, sitemap fetches, and rendered output for the release cohort. Compare those signals with the pre-release baseline.
Over the following days and weeks, review crawl statistics, index coverage, canonical selection, structured-data reports, impressions, clicks, and landing-page conversions. Segment dashboards by template or directory so a localized issue does not disappear inside sitewide averages.
Make rollback a product decision
A rollback plan should say what will be reversed, who can authorize it, and what evidence triggers action. High-risk releases might use thresholds such as widespread accidental noindex directives, unexpected 5xx responses on indexable routes, canonical changes affecting a major template, or a sharp rise in excluded pages tied to the deployment.
Not every ranking fluctuation warrants a rollback. Search demand and indexing timing vary. The decision should focus on confirmed implementation regressions and leading technical evidence, not a single day of position movement.
Maintain a release log with deployment time, commit or feature flag, affected URL patterns, baseline checks, production smoke-test results, and observed issues. These growth execution playbooks turn future incident response from guesswork into comparison against known changes.
Turn the Process Into a Repeatable Operating System
The most effective process is lightweight enough to run every week and structured enough to scale across teams. Store requirements and test fixtures in the same systems where product work already happens: tickets, pull requests, code repositories, release templates, and dashboards.
Create a reusable release template with risk tier, affected templates, acceptance criteria, fixture URLs, required approvals, monitoring links, and rollback owner. Review exceptions monthly: failed checks, bypassed gates, repeated defects, and pages that did not meet publication standards.
Distribution loops for SEO belong here too. When a page ships, confirm how it will be discovered: contextual internal links, hub pages, XML sitemaps, relevant product surfaces, and any editorial or partner distribution that is appropriate. Publishing without a discovery path makes otherwise strong pages slower to validate.
The process should evolve from incident evidence. If a canonical regression escaped, add a deterministic assertion. If reviewers repeatedly debate whether pages are thin, improve the content data contract. If staging differs from production, prioritize environment parity rather than adding more manual checks.
Key Takeaways
- Treat technical SEO as a release quality attribute, with named owners and observable acceptance criteria.
- Use risk tiers to match QA effort to template reach, especially for routing, SSR, canonicals, robots, and programmatic SEO.
- Test server-delivered HTML and route behavior in SSR React applications, not only hydrated browser output.
- Combine CI assertions, staging crawls, production smoke tests, monitoring, and explicit rollback criteria.
- Publish scaled pages only when data, uniqueness, indexation, and internal discovery requirements pass QA gates.
A reliable release process lets product teams ship faster with less search risk because quality checks are built into execution rather than added after traffic disappears.